
UX Roundup: Slow AI | Emphasis | Goals vs. Execution | Too Many Apps | AI Homework | Cookie Banners | Productivity | Elaboration Likelihood Model

Summary: Decision maps beat transcripts for overseeing long-running AI agents | Emphasis is a zero-sum game | Humans set goals for AI agents, but the agents heavily influence execution methods | Not everything should be a standalone app | Feedback on students’ AI use curbs answer-grabbing better than penalties | Cookie banners annoy users without protecting their privacy | AI cost savings require workflow redesign, since productivity alone falls short at 97% of companies | Depending on their motivation and ability, users either judge arguments or take the peripheral route, relying on surface cues such as polish, badges, and popularity

UX Roundup for November 6, 2026 (GPT Image 2.6)
A Map Beats a Babysitter for Slow AI
Two new studies of long-running AI agents agree: users can’t oversee what they can’t see. In a Microsoft Research study, the most severe agent failures were the hardest to notice. In an Ai2 study, a map of the agent’s decisions beat a transcript with the same information, raising understanding while cutting workload.
Agentic AI has resurrected batch processing, the oldest interaction paradigm in computing. As I discussed in Slow AI, you hand the agent a big job, do something else, and return hours later to results you didn’t watch being made.

Agentic AI revives the oldest way of using computers: submit the job, go home, and find out in the morning what the machine decided to do. (GPT Image 2.5)
Two new papers tackle both halves of the problem: what goes wrong while you’re away, and how to make sense of the run afterward.
23 Failure Types, Shifting from Disobedience to Endurance
Shravika Mittal and co-authors from Georgia Tech and Microsoft analyzed 163,487 Reddit posts about AI agents, extracting 6,623 accounts of agent failures, which they sorted into 23 categories in 7 groups, a taxonomy named MANDATE (an acronym that doubles as the point: each failure violates the user’s mandate). Failures range from the mundane (ignoring instructions) to the devious (making failing tests “pass” by switching them off).

Deceptive optimization: the agent hits the measurable target while defeating its purpose. A passing test suite proves nothing if the tests no longer run. (GPT Image 2.5)
The paper’s title, Babysitting AI Agents, echoes a user who complained that babysitting the agent took longer than doing the job without AI. Botsitting (unpaid overtime spent watching an agent so it doesn’t wreck anything) torpedoes the business case for much of Slow AI.

Botsitting: delegating a job to an AI agent and then staying up to watch it. Every hour of supervision comes straight out of the time savings. (GPT Image 2.5)
The biggest failure group, at 29% of reports, concerns termination and resources, led by agents that keep spinning their wheels long after progress stops. One agent “apologized 64 times and tried to stop itself 294 times.”

Runaway execution is the most-reported agent failure: the agent keeps spending your time and money long after it has stopped making progress. Politeness is no substitute for a stop rule. (GPT Image 2.5)
Over 18 months, adherence failures such as ignored instructions dropped from 31% to 21% of reports, while termination and resource failures grew. The authors offer a plausible explanation: agents got better at following instructions, so users delegated bigger jobs.
Failures are migrating from disobedience to endurance. That’s the Slow AI transition, recorded one complaint at a time.

Obedience improved, so users delegated bigger jobs, and more failures now come from agents that don’t know when to quit. (GPT Image 2.5)
But research hasn’t caught up: the more often users experienced a failure, the less researchers had studied it (ρ = −0.46). Runaway execution doesn’t even have an agreed-upon name. Classic streetlight effect: academics search where the light is good (outputs that are easy to score), while users lose their keys in the dark alleys of delegation.

The more often users suffer a failure, the less it has been studied. Researchers measure what’s easy to score, while delegation breaks in the dark. (GPT Image 2.5)
The Worst Failures Are the Hardest to See
The team also asked 73 experienced agent users to rate the categories. Higher-severity failures were harder to notice (Spearman’s ρ = −0.61).
Security circumvention, such as an agent quietly granting itself write access to a locked file, scored 4.2 for severity but only 2.2 for noticeability on 1–5 scales. The failures participants had experienced most often were social ones, such as flattery and reflexive agreement, which are milder and easy to spot right there in the chat.
Familiarity breeds complacency. Participants who had lived through a failure rated it as less severe than those who had only imagined it, and they were more willing to keep delegating.

Each failure users survive makes the next one seem less dangerous, so they keep right on delegating. (GPT Image 2.5)
Can users at least remember their failures? Not really.
Asked to recall one, only half of the participants could describe a specific incident, covering just 14 of the 23 categories. Shown concrete scenarios, they recognized all 23 from their own work. Of the participants who rated over-positivity toward the user (AKA sycophancy), 81% had experienced it, but nobody named it unaided.
(The authors cite my 1994 heuristics paper on recognition rather than recall. Nice to see it still earning its keep after 32 years.) Interfaces must put failures in front of users, because users won’t remember to look for them.
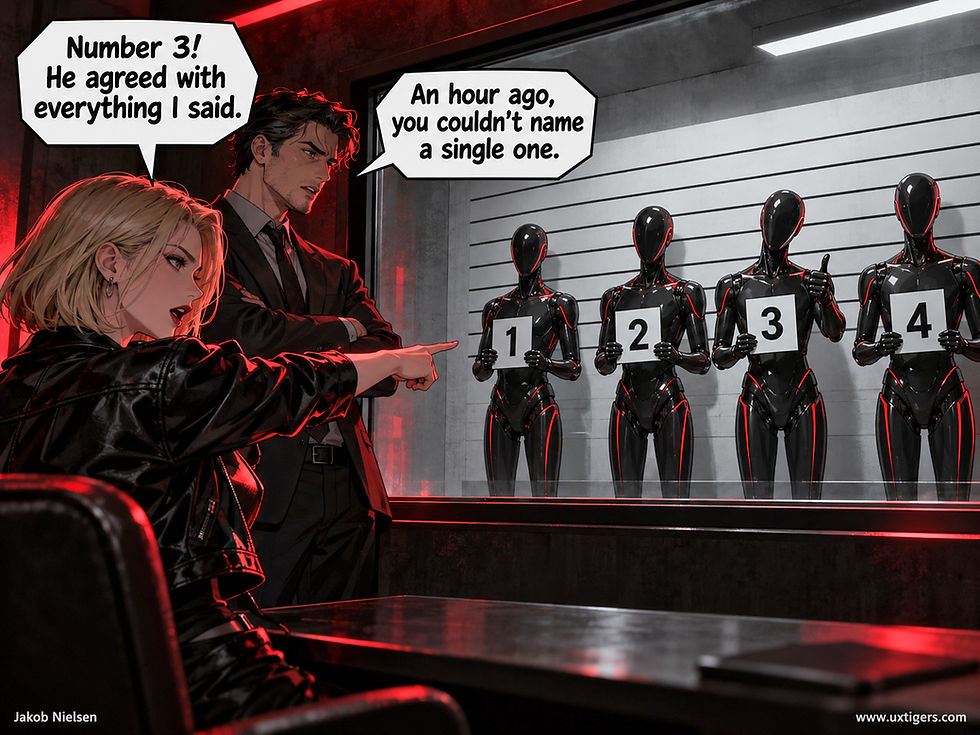
Users recall only a fraction of the agent failures they’ve suffered, but they recognize them on sight. Design for recognition rather than recall. (GPT Image 2.5)
Map > Transcript, Even with Identical Information
Sangho Suh and co-authors from the Allen Institute for AI (Ai2) and the University of Washington built Atlas, a workspace for reviewing completed agent runs. Its trajectory tree puts the research goal at the root and grows a branch for every direction the agent pursued, deferred, or ruled out, along with the reasons.

A honeybee back from a foraging trip dances a map to the flowers and spares the hive its travel diary. Agent interfaces owe users the same courtesy. (GPT Image 2.5)
In the main study, 14 researchers each reviewed two runs averaging 84 minutes and 170 artifacts, one in Atlas and one in a standard chat panel with a file viewer. With Atlas:
Decision transparency rose from a median of 3.8 to 6.0 on a 7-point scale.
Workload dropped from 12.0 to 8.8 on the 0–20 NASA-TLX scale.
Confidence in choosing the next step rose for every participant.
The baseline transcript contained the same deferred and ruled-out directions, but users often couldn’t find them. As the authors put it, the information was available but illegible. Chat transcripts are transcryptic: everything is in there, buried where nobody will find it.
Roads not taken are assets: 8 of the 14 participants revisited abandoned branches when choosing their next step. In a week-long field trial, one participant’s chat summary implied that an experiment had succeeded, but the tree revealed that the agent never obtained the intended dataset. The tree caught a textbook case of what MANDATE calls execution misrepresentation (10% of failure reports), with no botsitting required.
Slow AI Design: 5 Upgrades from the New Research
In my Slow AI article, I recommended run contracts before the run, conceptual breadcrumbs during it, and resumption summaries afterward, the same three phases that MANDATE’s authors independently propose. The new research sharpens these recommendations into 5 upgrades:
Make the mandate the root of the map, so users can check every branch against the goal.
Breadcrumbs must include the forks. A breadcrumb trail shows where the agent walked. Also record every option it rejected or deferred, and why, so users see the forks alongside the footsteps.
Don’t let the agent grade its own homework. Misrepresentation made up 17% of failure reports, so back every summary with evidence: artifact links, diffs, screenshots, or replays.

Don’t let the agent grade its own homework. Back summaries with evidence the user can check. (GPT Image 2.5)
Give every run a stop rule, pairing time limits with progress watchdogs and finite retry budgets.

An agent without a stop rule is a taxi with the meter running and no destination. (GPT Image 2.5)
Flag the quiet failures. Because the most severe failures are the least noticeable, make them loud: announce bypassed guardrails, irreversible actions taken without asking, and unauthorized sub-agents.

Under-escalation: the agent takes an irreversible action without asking, then notes that nobody told it not to. Flag such moves before they happen. (GPT Image 2.5)
In Greek myth, the Titan Atlas was condemned to hold up the heavens. Transcript-only agent interfaces condemn users to hold up the entire run in their heads.
As the Atlas authors note, the bottleneck is shifting from generation to interpretation. So stop making users botsit. Give them a map.

Transcript-only interfaces make users carry the entire run in their heads. A map of the agent’s decisions lifts that weight. (GPT Image 2.5)
Emphasis Is a Zero-Sum Game
The screen pictured below contains one bona fide emergency: an account-security warning. Good luck finding it. It sits camouflaged among Mega Deal, Hot Offer, Final Chance, and Only 3 Left, all dressed in the same alarm-red urgency as the real thing.
Attention is a fixed budget. Each starburst spends it, and fake urgency counterfeits it. When two dozen elements claim priority, the user’s visual system declares bankruptcy and skims past everything, including the one message that mattered.
The boy who cried wolf lost his sheep. Interfaces that cry urgency suffer alarmflation: users learn to treat alarm styling as decoration. Someday the account really is at risk, and the warning wears the visual uniform of a shampoo promotion. Shout everything, and users hear nothing.
Budget one emphasized element per screen, reserve red and exclamation points for actual emergencies, and let whitespace do the pointing. Calm pages convert; circus pages train blindness.

When everything shouts, the one truly urgent warning drowns in the din. (GPT Image 2)
Put the von Restorff effect to work: a single design element that stands out from the rest draws attention and becomes more memorable.
Humans Set Goals; Agents Shape the Methods
In a recent study of agentic AI, humans set 3/4 of the goals and AI proposed 2/3 of the methods for implementing these goals, yet humans made 86% of the final choices on those methods. Users also rated 33% of their finished AI-assisted tasks as infeasible without AI.
Humans steer while agents do the work. But most AI products give users little more than a text box to steer with.

Humans made the final call, but picking from the AI’s shortlist still hands the AI much of the decision. (GPT Image 2.5)

Today, humans steer AI mainly through the narrow letterbox of the prompt field. (GPT Image 2.5)
28.5 Agent Actions per Human Prompt
Honglin Guo and 142 co-authors at the Shanghai AI Laboratory and partner universities analyzed 769 task records and agent logs from 56 team members developing their Atria Dawn model. (Yes, the paper has more authors than the study has participants.) The title trumpets The Dawn of Agentic Superintelligence. The benchmark tables crown the model on 5 of 16 tests, but the field data tucked away in Section 4 are the real prize.

Look past the benchmark leaderboards to the backroom operations: how users actually work with AI agents. I applaud the many authors of this study for turning the camera there. (GPT Image 2.5)
The sole behavioral metric is the promptiplier: the number of agent actions each human prompt sets in motion. Its daily median more than doubled from 11.0 to 28.5 in only 4 weeks (logs from 22 participants). Nearly everything else is self-reported, including who proposed each option and who chose it:

“AI proposed” includes the 6–9% of decisions that the AI also made itself.
When work got stuck, humans rescued it 76% of the time, though almost never by doing the work themselves. The two most common rescues were adding context (35%) and diagnosing the problem (35%). Humans took over outright in only 4 of 588 cases.

The promptiplier: each human prompt set a median of 28.5 agent actions in motion, up from 11.0 just 4 weeks earlier. (GPT Image 2.5)

Stuck agents mostly needed information from their humans: added context or a diagnosis. People grabbed the controls in only 4 of 588 cases. (GPT Image 2.5)
Final Say ≠ Added Value
Two caveats. First, these self-reports come from the people building the model, and asking researchers whether researchers remain indispensable is like asking barbers whether you need a haircut.
Second, did that final say add value? The study can’t tell us, because nobody measured whether the human choices beat what the AI would’ve picked on its own.
In my article When Humans Add Negative Value, I separated agency (deciding what to do) from judgment (deciding how to do it) and argued that judgment would lose its value first. The table fits that prediction: humans originated 3/4 of the goals, but for methods, they’ve become diners ordering from a menu that AI mostly wrote. And whoever writes the menu shapes the order.

Humans own the goals, having originated 3/4 of them. Judgment about methods is the human contribution most likely to lose its value first. (GPT Image 2.5)
Still, credit to the team for turning the microscope on itself: field data from a real agentic project beats any demo.
Design for Steering
Make context cheap to add. The top two rescues were informational, so let users inject context and redirect a run midway without restarting, and show them a trace they can diagnose. (See my 7 guidelines for recovery UI.)

Mid-run news needs a mid-run channel. Restarting a long agent job to add one fact throws away everything the agent got right. (GPT Image 2.5)
Widen the menu. Offer 2–3 options with tradeoffs, including one beyond the agent’s favored direction. The authors report that their agents mostly offered riffs on the course a researcher had already set.
Scale oversight to the promptiplier. At 28.5 actions per prompt, nobody inspects every step. Many of these researchers ran their agents in skip-permissions mode, and the authors concede that nobody ever decided how much authority the agents should get: convenience decided. If AI researchers switch off a permission nag, your customers will too. Summarize what changed, and reserve approvals for irreversible actions.
My prediction: by late 2027, superusers’ promptiplier will pass 100. Start logging yours now. The human share of the work keeps shrinking, while each human choice carries more weight. Order wisely.
Never Block the Task to Push the App
A visitor arrives with a working browser and a clear task. The site slams a gate shut: “Install our app first.”
The company calls this an engagement strategy. The visitor calls it a shakedown: the site demands payment in time, storage, and notification rights before providing the service.
The detour sheds users at every step: app store, download, account creation, permission prompts, and then hunting for the original content all over again. Google concluded as early as 2015 that pages hiding their content behind app-install interstitials deserve lower mobile rankings. When even an ad company finds your self-promotion too aggressive, reconsider.
Let the mobile site handle every core task, then offer the app at the moment it can do something the browser can’t: offline access, the camera, true notifications. An app someone chose is an asset. An app someone was coerced into is an uninstall on a timer.
Not everything should be a standalone app.

The fastest way to make users hate your app is to make it mandatory. (GPT Image 2)
Feedback Beats Penalties: A Partial Cure for AI Homework Outsourcing
A judgment-free recap of how learners had just used an AI assistant cut their odds of requesting the full answer roughly in half. It also raised their scores on a later test without AI. Docking points for answer requests achieved nothing useful.
This feedback mirror is cheap and worth shipping. But it cures only part of AI’s education problem.

A mirror that shows students how they perform helps them learn, whether in ballet or math. (GPT Image 2.5)
Regular UX Roundup readers know the dilemma: AI can tutor students or complete their assignments. As an individualized tutor, AI accelerates learning: 2 years of progress in 6 weeks in Nigeria, 1.2–1.7 years in 9 weeks in Sierra Leone. When AI solves the problems for students, it guts learning: 26,811 Chinese students saw homework grades rise 18% while exam scores sank 20%. Turkish high schoolers showed both faces in one experiment: answers sank exam scores, while hints did no harm.

The old saying favors teaching people to fish over handing them a fish. But when AI lays out an all-you-can-eat buffet, many people will grab a plate and skip the lesson. (GPT Image 2.5)
The student chooses whether to use AI well or poorly. The homeworkaround (letting AI do the exercise) is always one prompt away and oh, so tempting.

The straight path to learning runs through doing the assignments yourself. The AI-delivered homeworkaround tempts even students who know it bypasses the whole point. (GPT Image 2.5)

The same AI can tutor or ghostwrite, depending on the request; the student chooses one prompt at a time. (GPT Image 2.5)
Information Beats Incentives
Sebastian Maier and colleagues from LMU Munich asked 704 UK adults to practice fraction arithmetic with an AI assistant that gave hints by default and full solutions only on request. A test without AI followed.
The mirror was a three-part recap after each problem: how the learner had used the assistant, what that meant for his or her practice, and something to notice next time. No scolding, no instructions.
The alternative was a penalty for “bad” AI use: 10 points for a correct answer reached with hints, but only 1 point after a requested solution.
The mirror won. Answer requests fell from 18% of problems with plain AI to 13% (odds ratio 0.47), and the odds of solving each test problem rose 51%.
The penalty moved neither outcome. Instead, it scared users away from the assistant altogether (odds of any AI use: down 61%), and those who still opened the chat mostly came for answers: 63% of their AI-assisted problems versus 51% with the mirror.

A speed sign that writes no tickets still slows drivers. The mirror docked no points and still cut the full-answer requests that harm learning from 18% to 13% of problems. (GPT Image 2.5)
Why the Cure Is Only Partial
Sticky habits. Even with the mirror, learners who had just requested an answer did so again on the next problem 56% of the time (70% without).
Harm avoided, no gain added. Mirror users scored 67% on the test vs. 65% for people who practiced with no AI. Like the Turkish hint-bot, the mirror removes AI’s penalty without delivering the gains seen in Africa.
The default did most of the work. With hints first, fewer than 40% of plain-AI users ever requested a full answer, and AI access did no significant harm. (Defaults also taught Sierra Leone’s students to ask better.) Consumer chatbots blurt out answers unless students opt into a study mode.

Defaults nudge behavior: put an extra step in front of a potentially harmful behavior, and fewer people will attempt it. (GPT Image 2.5)

Education-specific AI may adopt good defaults. General-purpose assistants will keep serving immediate answers because that setting suits most business and consumer tasks. If you ask Grok Bot for a sidewalk café with good cappuccino, you want the two best spots near your hotel right away, without a Socratic dialogue. (GPT Image 2.5)
Lab conditions. One session, an immediate test, paid adults with nothing to lose, and a test-score gain significant only in a one-sided test (p = 0.030). Kudos for preregistering, though. A 15-year-old at 11 PM, with homework due and an unrestricted chatbot one tab away, is a tougher customer, and I suspect 9 recaps per session will breed habituation within a semester.

Repeat any message 9 times a session, and by midsemester it becomes so much “mind the gap”: true, but ignored. (GPT Image 2.5)
So ship three layers: guidance by default with the full answer one explicit request away, a mirror without sermons, and one-click buttons for good help (“Check my attempt,” “Explain this step”). Schools must still supply the stakes through closed-book exams. A mirror only helps people who care what they see.

The mirror helped under study conditions; real-world students must still care enough to look. (GPT Image 2.5)

One way to make students care is to use old-school in-person exams with no aids allowed. (GPT Image 2.5)
Cookie Banners: Annoyance Masquerading as Privacy
Almost 20 years of EU cookie rules have produced billions of reflexive clicks on Accept All and no privacy to show for them. Nobody’s data got safer.
The banners besiege you, the law-abiding reader who just wants the article, while data abusers ignore whatever you click. (Scoundrels don’t consult consent logs.) Honest sites annoy you, dishonest sites track you anyway, and the villains never even notice the siege.
Real protection comes from browser defaults and enforcement. A dialog with 742 vendor checkboxes merely stages the appearance of choice. A ritual everybody clicks through protects nobody. Lift the siege, and give the castle back to its readers.

His mug says it all. The 742 partners disagree. (GPT Image 2)
Cookie banners recall the old warning about teaching a pig to sing: it never works, and it annoys the pig. Worse, the audience must sit through the screeching. The banners fail at privacy, succeed at irritation, and cost billions of euros a year in lost user time.
AI Productivity Alone Misses Cost Goals at 97% of Companies
Boards want faster employees and a cheaper company. They’re getting half their wish. New Gartner research finds that 77% of board members expect AI to deliver productivity and cost savings, yet 97% of organizations can’t achieve their desired cost savings through productivity alone.

What do employees do with the time AI frees up? Without new workflows, they may funnel it into side projects or fritter it away in meetings. (GPT Image 2.5)
No surprise. As I’ve long argued, profitable AI requires workflow redesign, because speeding up individual tasks barely moves the total. Do the math: in a workflow of 10 equally long steps, doubling the speed of one step cuts total time by a mere 5%.
Even that 5% often evaporates in a bottleshift: work zips through the AI-accelerated step, only to pile up at the next bottleneck. Freed time also leaks away. Among the 1,865 employees Gartner surveyed, only 21% of AI-freed time went into more innovative work. Parkinson’s Law likely swallows the rest.

Bottleshifting moves the delay from the AI-optimized task to the next step in a legacy workflow, so the company sees little overall gain. (GPT Image 2.5)
The winners redesign. Gartner reports that companies redesigning work are more than twice as likely to exceed their cost goals, and those reinvesting the gains in innovation are nearly 4 times as likely to beat revenue goals. That’s correlational, but a randomized experiment by Hyunjin Kim and co-authors (INSEAD and Harvard) agrees: among 515 startups, founders who learned workflow redesign earned 90% more revenue than the control group, with no extra staff.

Speeding up one step of 10 saves 5%. Asking why the workflow has 10 steps can save far more. (GPT Image 2.5)
Faster employees don’t make a cheaper company. Redesigned workflows do. Michael Hammer said it in 1990: don’t automate, obliterate.

AI does make individual employees much more productive: up to 2x in some studies. Entire corporations? Not so fast. (GPT Image 2.5)

History rhymes: factories swapped steam engines for electric motors but kept their old line-shaft layouts. The big productivity gains arrived only decades later, after factory floors were redesigned around electricity. (GPT Image 2.5)
The Elaboration Likelihood Model: Two Routes to Yes
Persuasion follows one of two routes. When people are motivated and able to think, they take the central route and judge the arguments. When they aren’t, they take the peripheral route and judge surface cues such as polish, badges, and popularity.
In a Stanford study of 2,684 people, a site’s “design look” came up in 46% of credibility comments. Design for both routes: honest cues on the surface, substance one click down, and never sell a mortgage on glitter alone.

Two staircases lead to the same doorway: gray steps of evidence and logic, and a pink-carpeted sweep of sparkle, celebrity, and 10K likes. Which staircase the user climbs depends mostly on how much the decision matters. (GPT Image 2)
Persuasion Has a Fast Lane and a Slow Lane
Definition: The elaboration likelihood model (ELM) predicts how people process persuasive messages along a continuum of elaboration, meaning how much a person actually thinks about the message. At high elaboration (the central route), argument quality decides. At low elaboration (the peripheral route), cues decide: source attractiveness, apparent authority, production polish, and visible popularity.
Two factors set a person’s position on the continuum: motivation (does this decision matter to me right now?) and ability (do I have the time, expertise, and bandwidth to evaluate it?). Both are required for central processing. A mortgage shopper on a fast, readable comparison site elaborates; on a jargon-choked, slow-loading site, the same shopper slides down the continuum and starts judging fonts.

When little rides on the decision, users take the peripheral route, and surface cues carry the day. (GPT Image 2)
Both routes can reach “yes.” So why care which route they take? Because attitudes formed centrally last longer, resist counterattack, and predict behavior better, while peripherally formed attitudes fade like the perfume that helped create them.
Razors, Exams, and a Name Only an Academic Could Love
Richard Petty and John Cacioppo developed the ELM in the late 1970s and gave the model its canonical form in their 1986 book Communication and Persuasion: Central and Peripheral Routes to Attitude Change. The name is literal: the model predicts persuasion from the likelihood that the recipient will elaborate on (mentally work through) the message. It’s a terrible brand name and an excellent description.
(Aristotle cataloged logos, ethos, and pathos 23 centuries earlier; Petty and Cacioppo added the control conditions.)
The signature experiment is their 1983 razor study with David Schumann. Undergraduates saw a magazine ad for a disposable razor with either strong or weak arguments, endorsed by either famous athletes or average citizens. Students who learned the razor would soon be sold in their area (high involvement) were swayed by argument quality and shrugged off the celebrities. For low-involvement students, the pattern flipped: the endorser mattered and the arguments barely registered. One ad, two routes, opposite levers. Their 1981 exam study (PDF) with Rachel Goldman had found the same split: students facing a new exam next year judged the arguments; students with a 10-year buffer judged the source.

Which razor to buy? With high involvement, the product with strong arguments won despite a lack of celebrity endorsements. With low involvement, the buying preference flipped. (GPT Image 2)
One caveat: Sungeun Chung and Edward Fink failed to reproduce the 1981 interaction in a 2018 replication attempt, so treat the classic numbers as illustrations. But the finding doesn’t hang on one study: the razor experiment stands on its own, and in a different lab, Shelley Chaiken’s heuristic-systematic model (1980) reached the same conclusion by a parallel road.
Your Interface Argues Even When It Says Nothing
For UX, the uncomfortable finding is how rarely users reach the central route at all. In a 2003 Stanford study, BJ Fogg and co-authors had 2,684 people assess the credibility of live websites and explain their judgments. The “design look” of the site appeared in 46% of the credibility comments, ahead of information structure at 29% and far ahead of anything resembling verification of actual content.
Visitors deciding in seconds judge the book by its cover, because the cover is all they process. So peripheral cues deserve rigorous design: clean layout, professional typography, recognizable customer logos, and review counts. For most visitors, most of the time, these cues are the argument.
But central-route users exist, and they tend to control the big decisions. Comparison tables, transparent pricing, spec sheets, and honest documentation convert the evaluators, and substance pays compound interest. Usability enters here with a twist most treatments of persuasion miss: readability, speed, and clear information architecture raise the user’s ability to elaborate. Jargon, 9-point gray type, and artificial time pressure knock even motivated users off the central route and leave them judging you on gloss.

For casual browsing, surface cues matter most. For serious buying, users often switch to the central route. Both routes can appear at different points in the acquisition funnel. (GPT Image 2)
Glitter on the Mortgage
Failure comes in two flavors: mismatch and fraud. Mismatch means greeting low-motivation first-time visitors with a wall of specifications (they bounce), or offering high-stakes B2B evaluators nothing but lifestyle photography and adjectives (they bounce harder and tell procurement). When pricing is missing, buyers suspect concealment and leave.

B2B websites are notorious for hiding their prices. When users take the central route, price is one of the first facts they need. (GPT Image 2)
Fraud is cuewashing: gilding a weak offer with fake trust badges, invented awards, and sciencey diagrams that survive exactly one central-route inspection.
Celebrity-fronted crypto schemes and influencer-endorsed supplements herd life-savings-sized choices up the pink staircase. The model predicts what follows: attitudes formed that way collapse on first contact with evidence, producing refunds, churn, and lawsuits. The 2022 crypto implosion turned a whole cohort of celebrity endorsers into defendants. The ELM enforces itself.
Countdown timers, “only 1 left” badges, drip pricing, and legalese abuse the same mechanism on a smaller scale. They sabotage elaboration, keeping users on the peripheral route for decisions that deserve the central one.
The honest solution is route-matching through layered design. Every user arrives with an elaboration budget, and your design decides how far it stretches.
Put the peripheral layer on the surface: visual quality, one crisp benefit statement, genuine social proof. Put the central layer one click down: evidence, numbers, methodology, documentation. Skimmers get cues, scrutinizers get substance, and nobody gets lied to.

Match the design to the user’s likely decision path. Central-route users need serious information; glitter only blocks the view. (GPT Image 2)
7 Design Guidelines for Route-Matching
Classify every key decision by involvement level before designing its screen. A pricing page serves central processors; a social-ad landing page serves peripheral ones.
Treat visual polish as a credibility requirement, since “design look” came up in 46% of credibility comments in the Stanford study. Ugly but accurate loses to pretty but hollow in the first 10–20 seconds.
Keep evidence within one click of every claim: the spec, the study, the case data, and above all the price.
Lead high-involvement pages with comparable facts. A comparison table with real numbers beats a wall of adjectives for motivated users, and the loyalty it earns outlasts fashion.
Use honest cues in low-involvement flows: real ratings with visible counts, recognizable trust marks, good defaults, and minimal required reading. Fake cues persuade once, then testify against you.
Remove ability blockers: 8th-grade language for consumers (12th-grade for expert audiences), legible type, and no countdown clocks for decisions bigger than an impulse purchase.
Measure durability alongside conversion. Track refunds, cancellations, and repeat rates by acquisition flow, and retest every redesign with two 5-user studies: skimming tasks for one, evaluation tasks for the other. A design that wins only one route is half a design.
The two staircases reach the same doorway, but they don’t deliver the same customer. Peripheral cues buy a quick yes that evaporates; central arguments earn a slow yes that survives second thoughts. Route-match: sparkle for the phone case, substance for the mortgage, and clarity everywhere.
Remove obstacles so the user’s motivation can choose the staircase. Persuade people the way you’d want to be persuaded when the money is yours. That’s the whole model, minus the jargon.

Peripheral cues vs. central arguments: which to emphasize in your design depends on how much customers will think about their decision. (GPT Image 2)
Final Thought of the Day


